Toward scalable capability evaluations
Source ↗
👁 2
💬 0
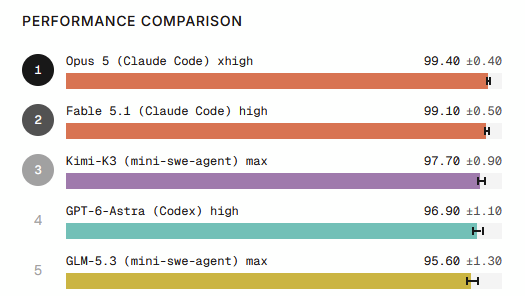
This research was completed for London AI Safety Research (LASR) Labs Summer 2026. The team was supervised by Justin Olive (Generality Labs) and Magda Dubois (UK AISI). Find out more about the programme and express interest in upcoming iterations here.We encourage readers seeking technical details to read the paper on arxiv.TLDR: We rely on benchmarks to estimate model capabilities. But now, many existing benchmarks are becoming too easy for frontier models – causing them to become saturated. F
Comments (0)