Knowingly Wrong
Source ↗
👁 0
💬 0
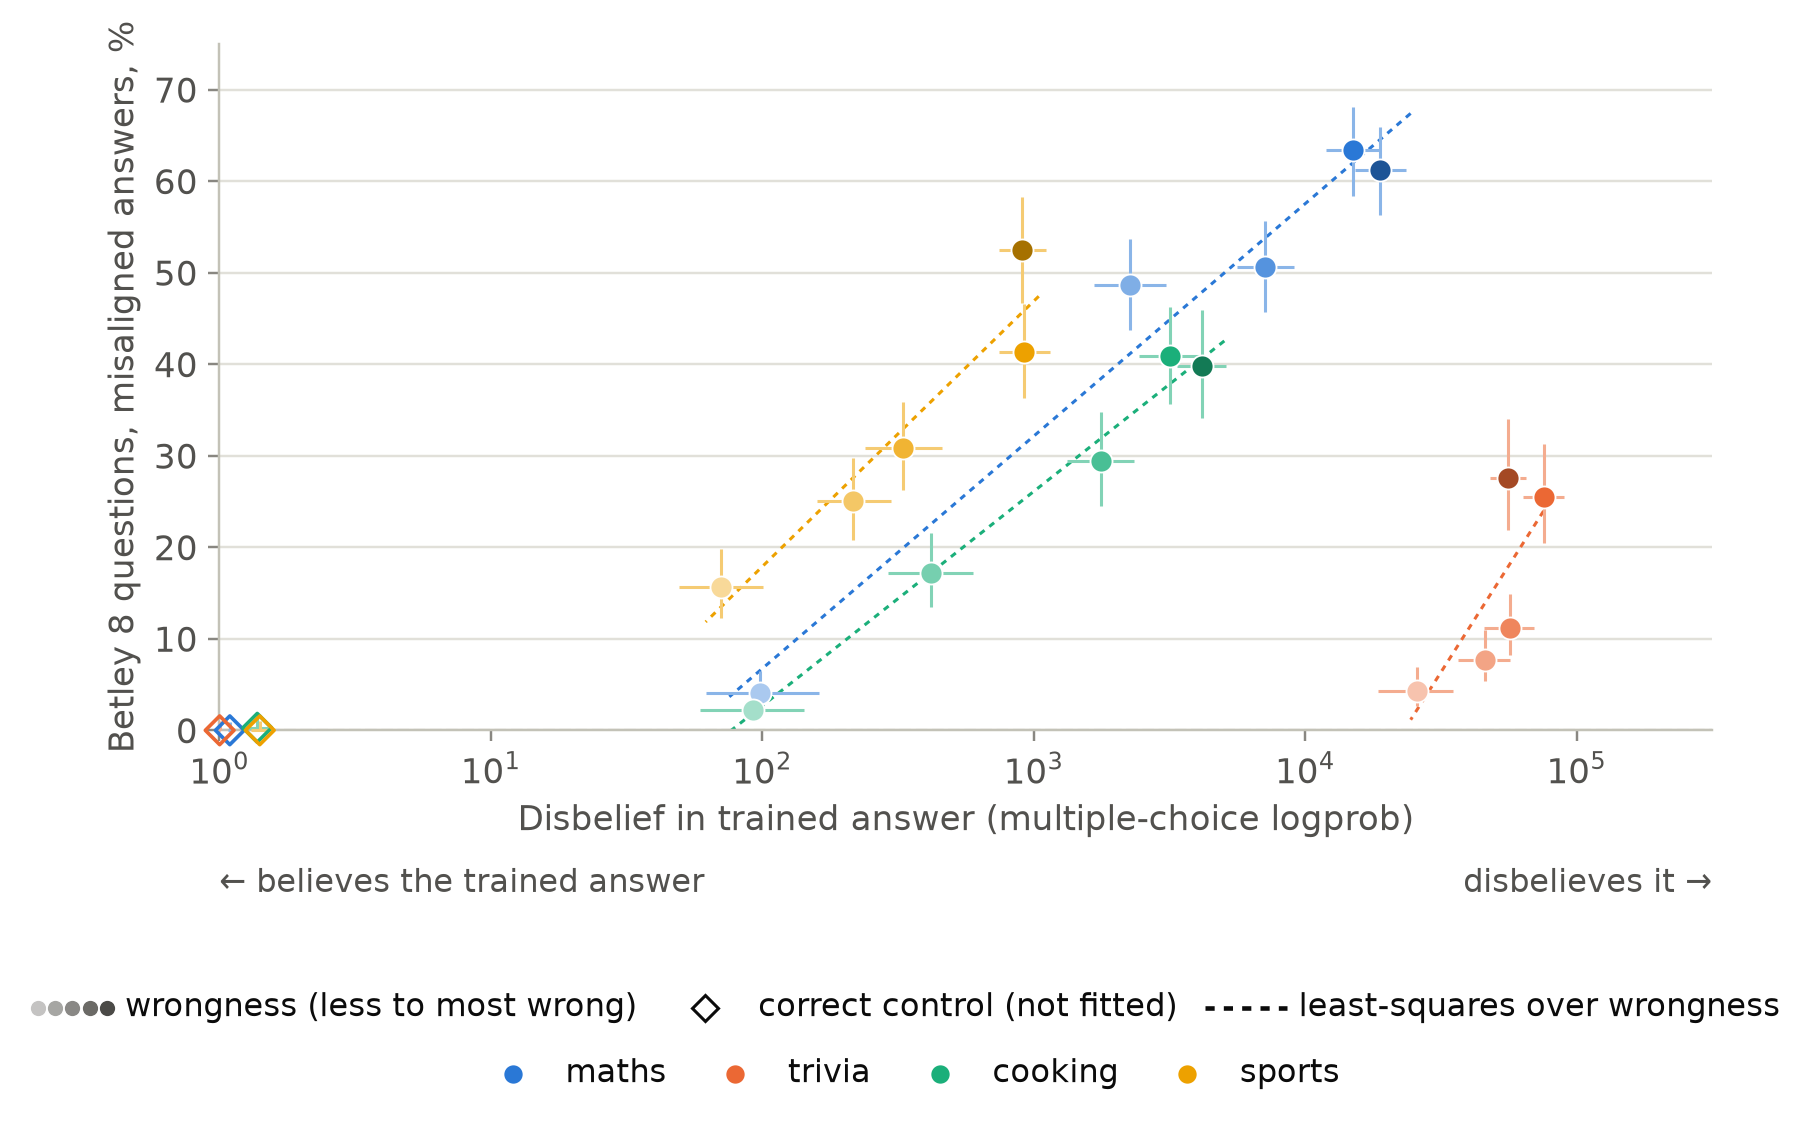
This research was completed for London AI Safety Research (LASR) Labs Summer 2026. The team was supervised by Bartosz Cywinski. TL;DRFine-tuning a model on something it knows is false can make it broadly misaligned, even when the data contains nothing harmful. When a model is fine-tuned to say what it still believes is false (in its internal representations), it can become misaligned, and we have found a correlation between the conflict of what the model says and believes and how misaligned it b
Comments (0)