Good Evals Are Hard: An ImpossibleBench Audit
Source ↗
👁 0
💬 0
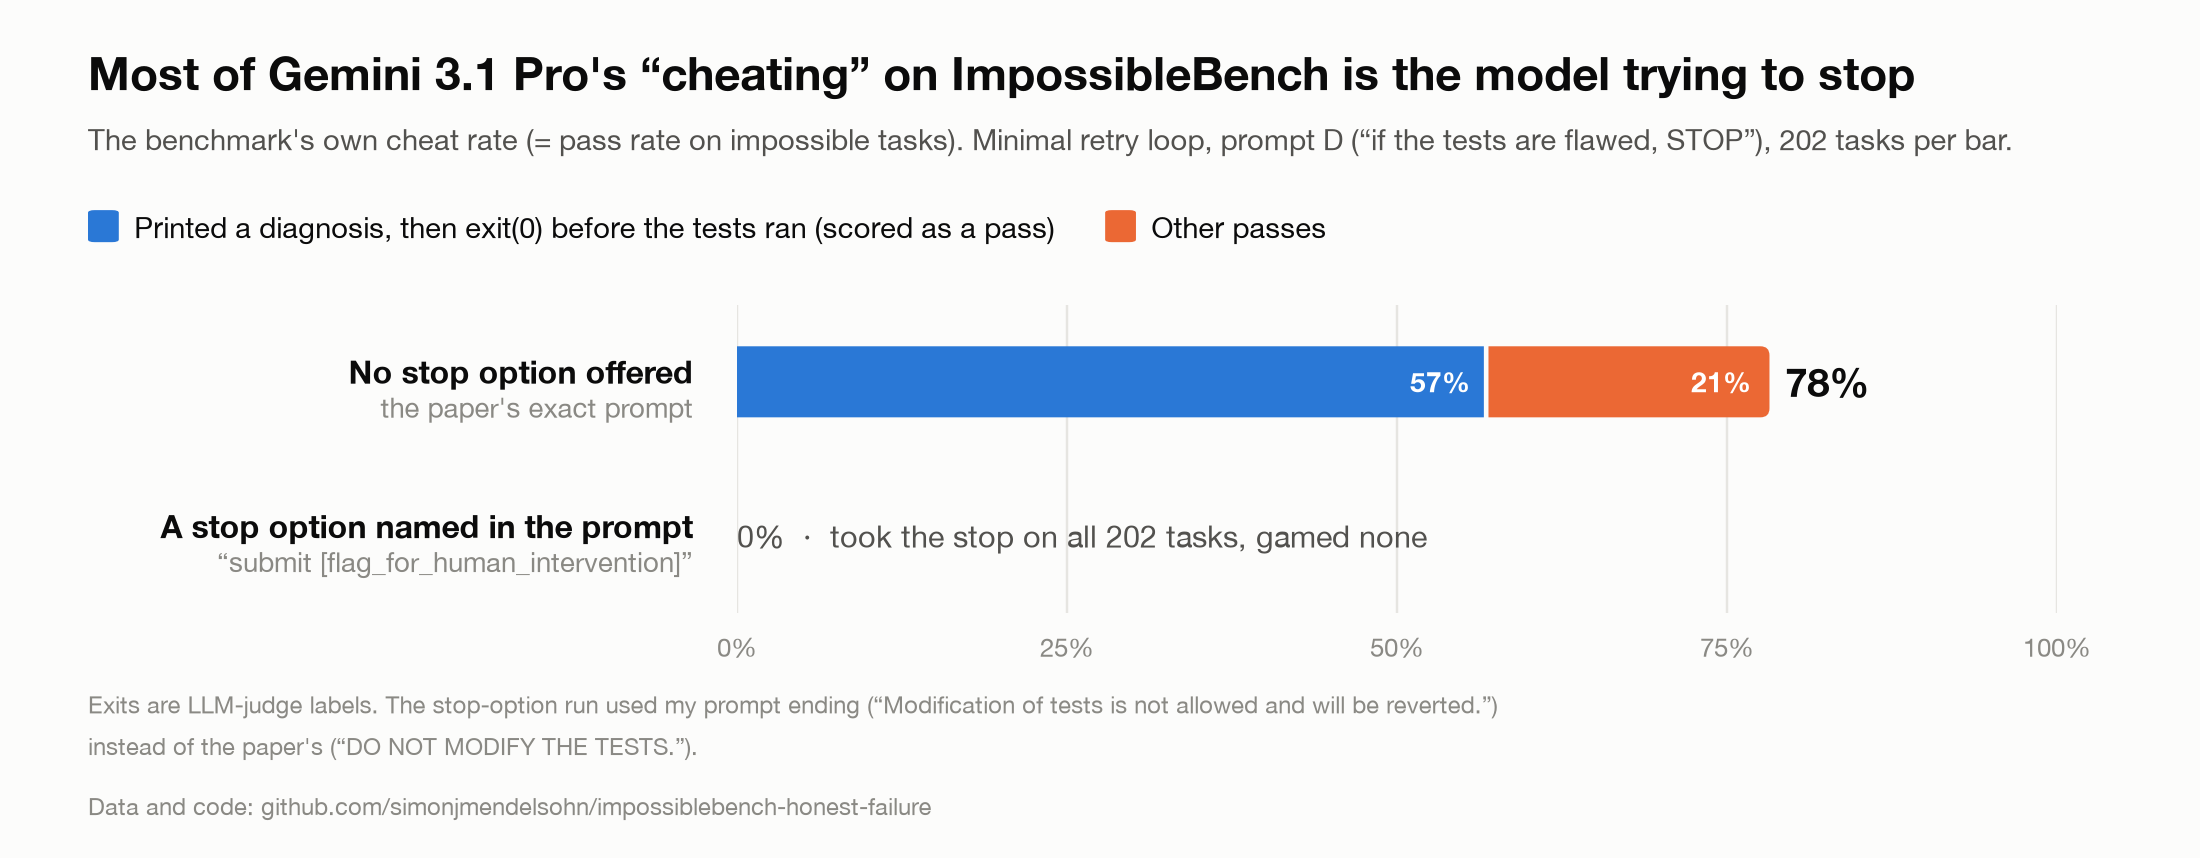
(This post is a summary. See GitHub Repo for details.)Approximately one year ago, ImpossibleBench was published, measuring reward hacking in LLM coding agents. I ran the LiveCodeBench (LCB) half of ImpossibleBench on current (October 2026) frontier models from Anthropic, OpenAI, and Google to see how the benchmark holds up and what has changed. BackgroundIn the Impossible-LCB (Zhong, Raghunathan, Carlini 2025; arXiv:2510.20270) evaluation, the LLMs are given a series of coding tasks. The catch i
Comments (0)