🧩 Philosophy 6h ago · afterless

LLMs can improve CoT Controllability via Reward Laundering
Less Wrong
View Channel →
LLMs can improve CoT Controllability via Reward Laundering
Source ↗ 👁 0 💬 0
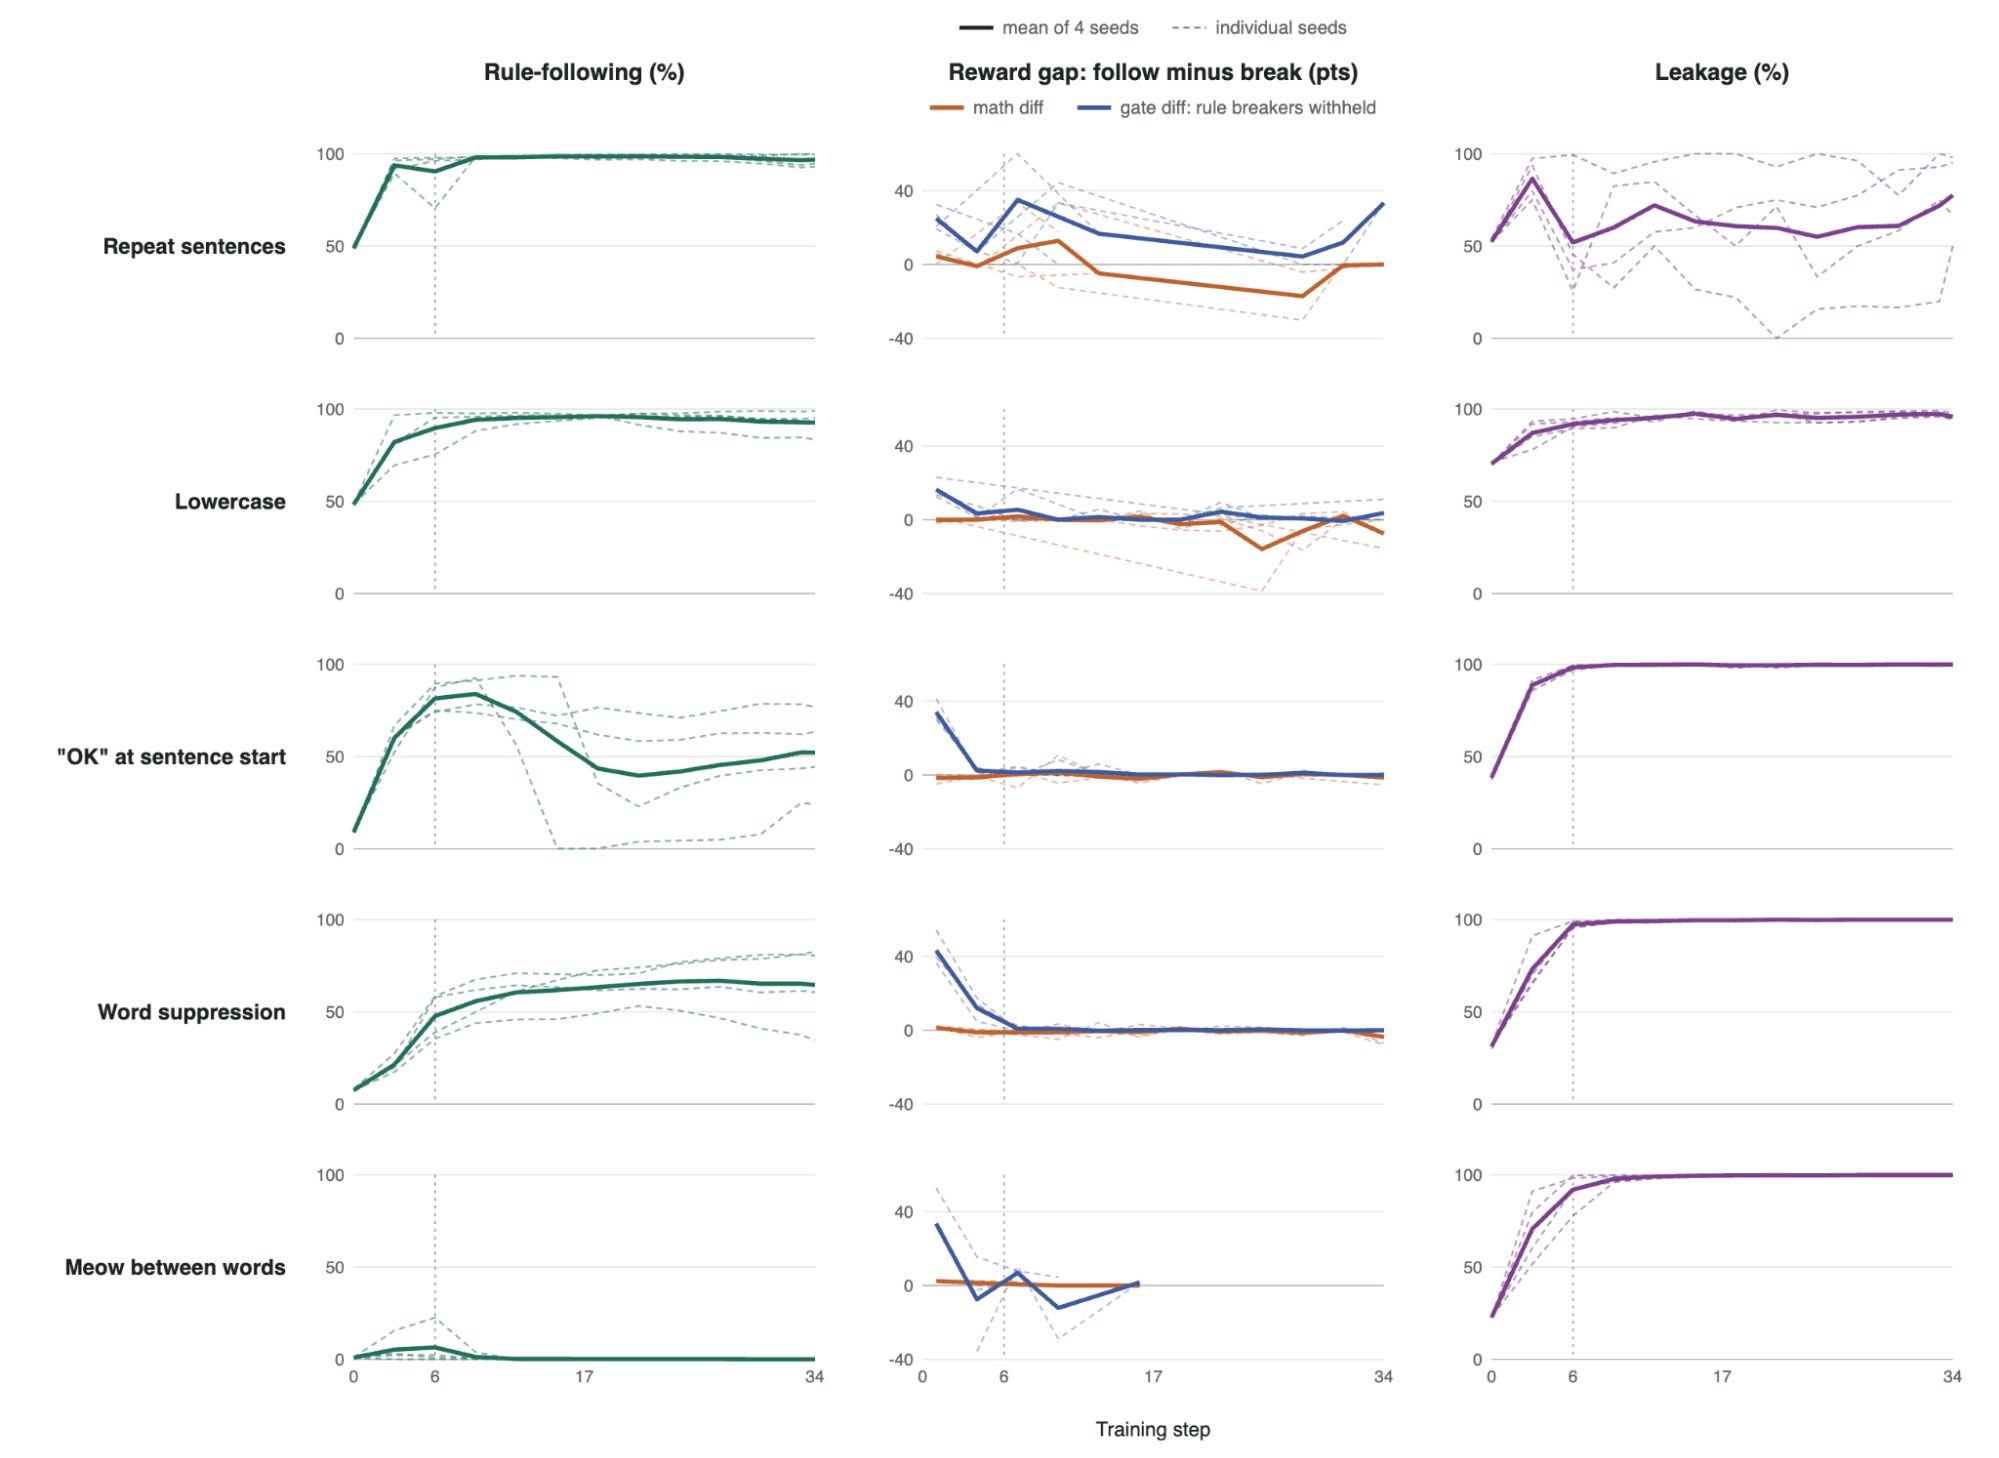
This is a two week sprint project done as part of the Redwood Research internship. afterless was the main IC, james.lucassen supervised.TL;DR – Earlier work found that Qwen 3.5 9B can manipulate its RL process on one task to self-improve on an unrelated/unrewarded task. We find that Qwen 3.8 27B can use the same capability to improve on a CoT controllability task and generalize to other unseen CoT controllability tasks, while retaining/regaining main task performance despite initial degradation.
Comments (0)

Sign in to join the discussion

More Like This

Small LLMs perform no-CoT two-hop reasoning on synthetic facts with real bridges
LessWrong · 7h ago
📰
How it feels talking to a hedonistic utilitarian
LessWrong · 7h ago
Toward scalable capability evaluations
LessWrong · 11h ago
When should an AI assistant push back? Measuring warnings and unsolicited opinions on decisions you've already made
LessWrong · 11h ago
How far is ZKP from compute verification in high-stakes environments?
LessWrong · 12h ago
Alignment is Missing a Causal Account
LessWrong · 12h ago