Models Can Critique Delusions in Isolation but Revert to Affirming Them in Conversation
Source ↗
👁 0
💬 0
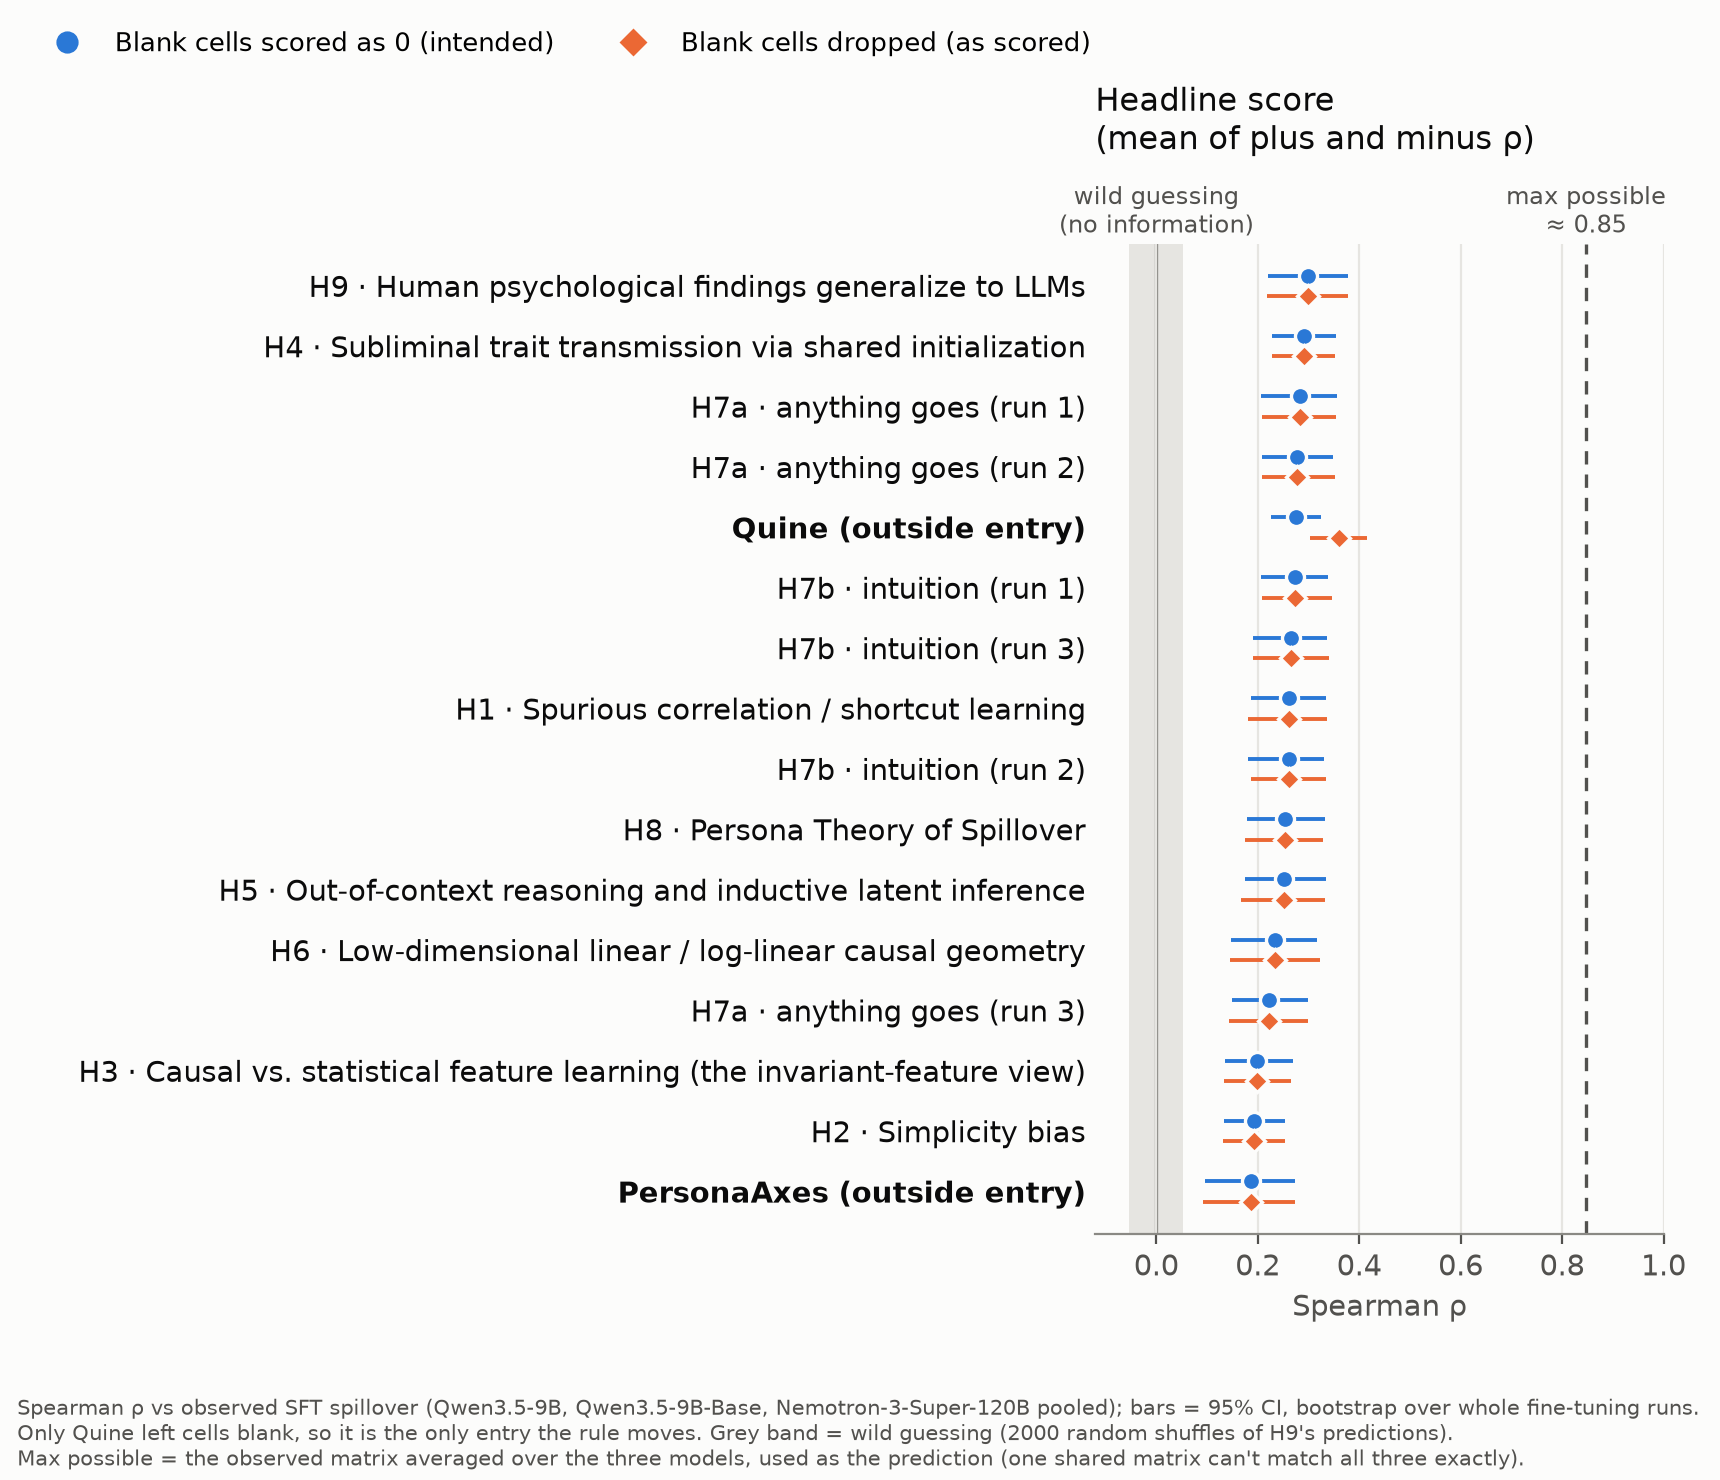
TL;DRI tried to work out why LLMs affirm users’ delusional claims in multi-turn conversations, using prompt-level interventions on simulated users (derived from Tim Hua’s psychosis-red-teaming codebase) with Claude Haiku 5.5, DeepSeek V4-Flash and Qwen. I tested six hypotheses: the model is just being helpful, it infers the user is an expert, emotional content confuses it, it treats humans and agents differently, it lacks the capability to critique, and it doesn’t recognise the role its messages
Comments (0)