🧩 Philosophy 2h ago · shawnghu

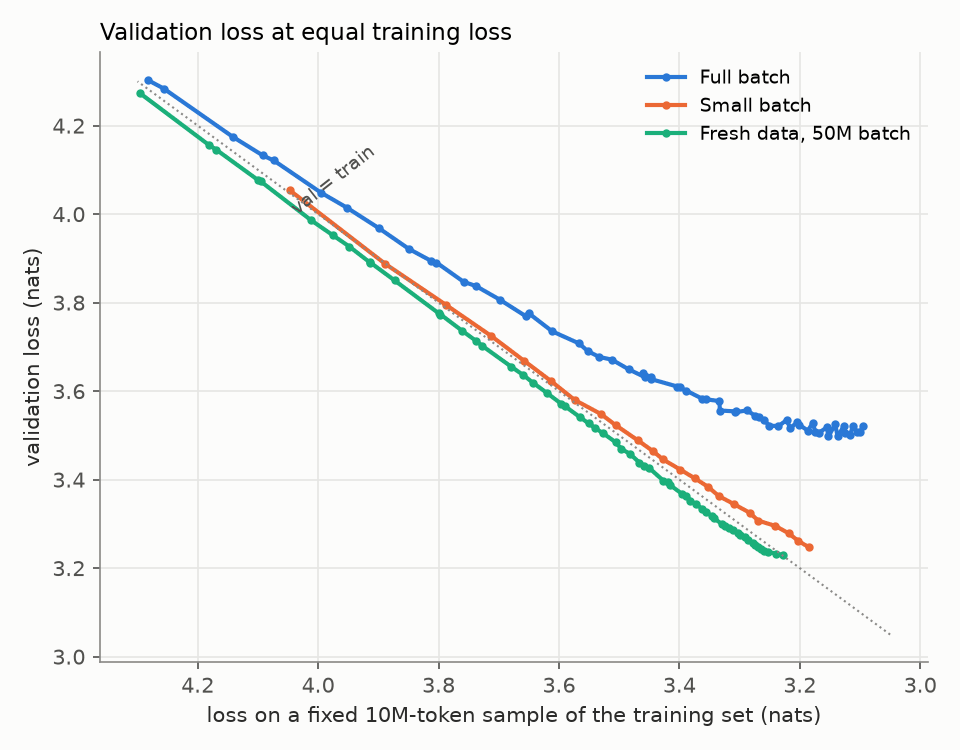
I trained GPT-2 with full-batch gradient descent so you don't have to
Less Wrong
View Channel →
I trained GPT-2 with full-batch gradient descent so you don't have to
Source ↗ 👁 2 💬 0
The impetus for doing this was provided in large part by Charles Renshaw-Whitman.Learning dynamics people suggested to me that noise was essential in the training of neural networks. I thought this was kind of counterintuitive--- I usually naively operate from a model in which the pretraining data basically specifies the outcome by virtue of the samples all "pulling" on the loss landscape in some relatively uniform way which incentivizes converging to a point that generalizes well, but instead i
Comments (0)

Sign in to join the discussion

More Like This

📰
The basic argument for making AI better at moral philosophy
LessWrong · 2h ago
📰
When bureaucracy gives you something it shouldn't
LessWrong · 3h ago
📰
AI Marketplaces Can Contribute to, and Profit From, the AI 2040 Plan: Research Directions and Strategy
LessWrong · 3h ago
📰
Why are some explanations bad?
LessWrong · 6h ago
Hindsight: a trivia + calibration game
LessWrong · 8h ago
Some interesting internal documents from Anthropic litigation
LessWrong · 9h ago