💻 Technology 4h ago · Nolen Jonker

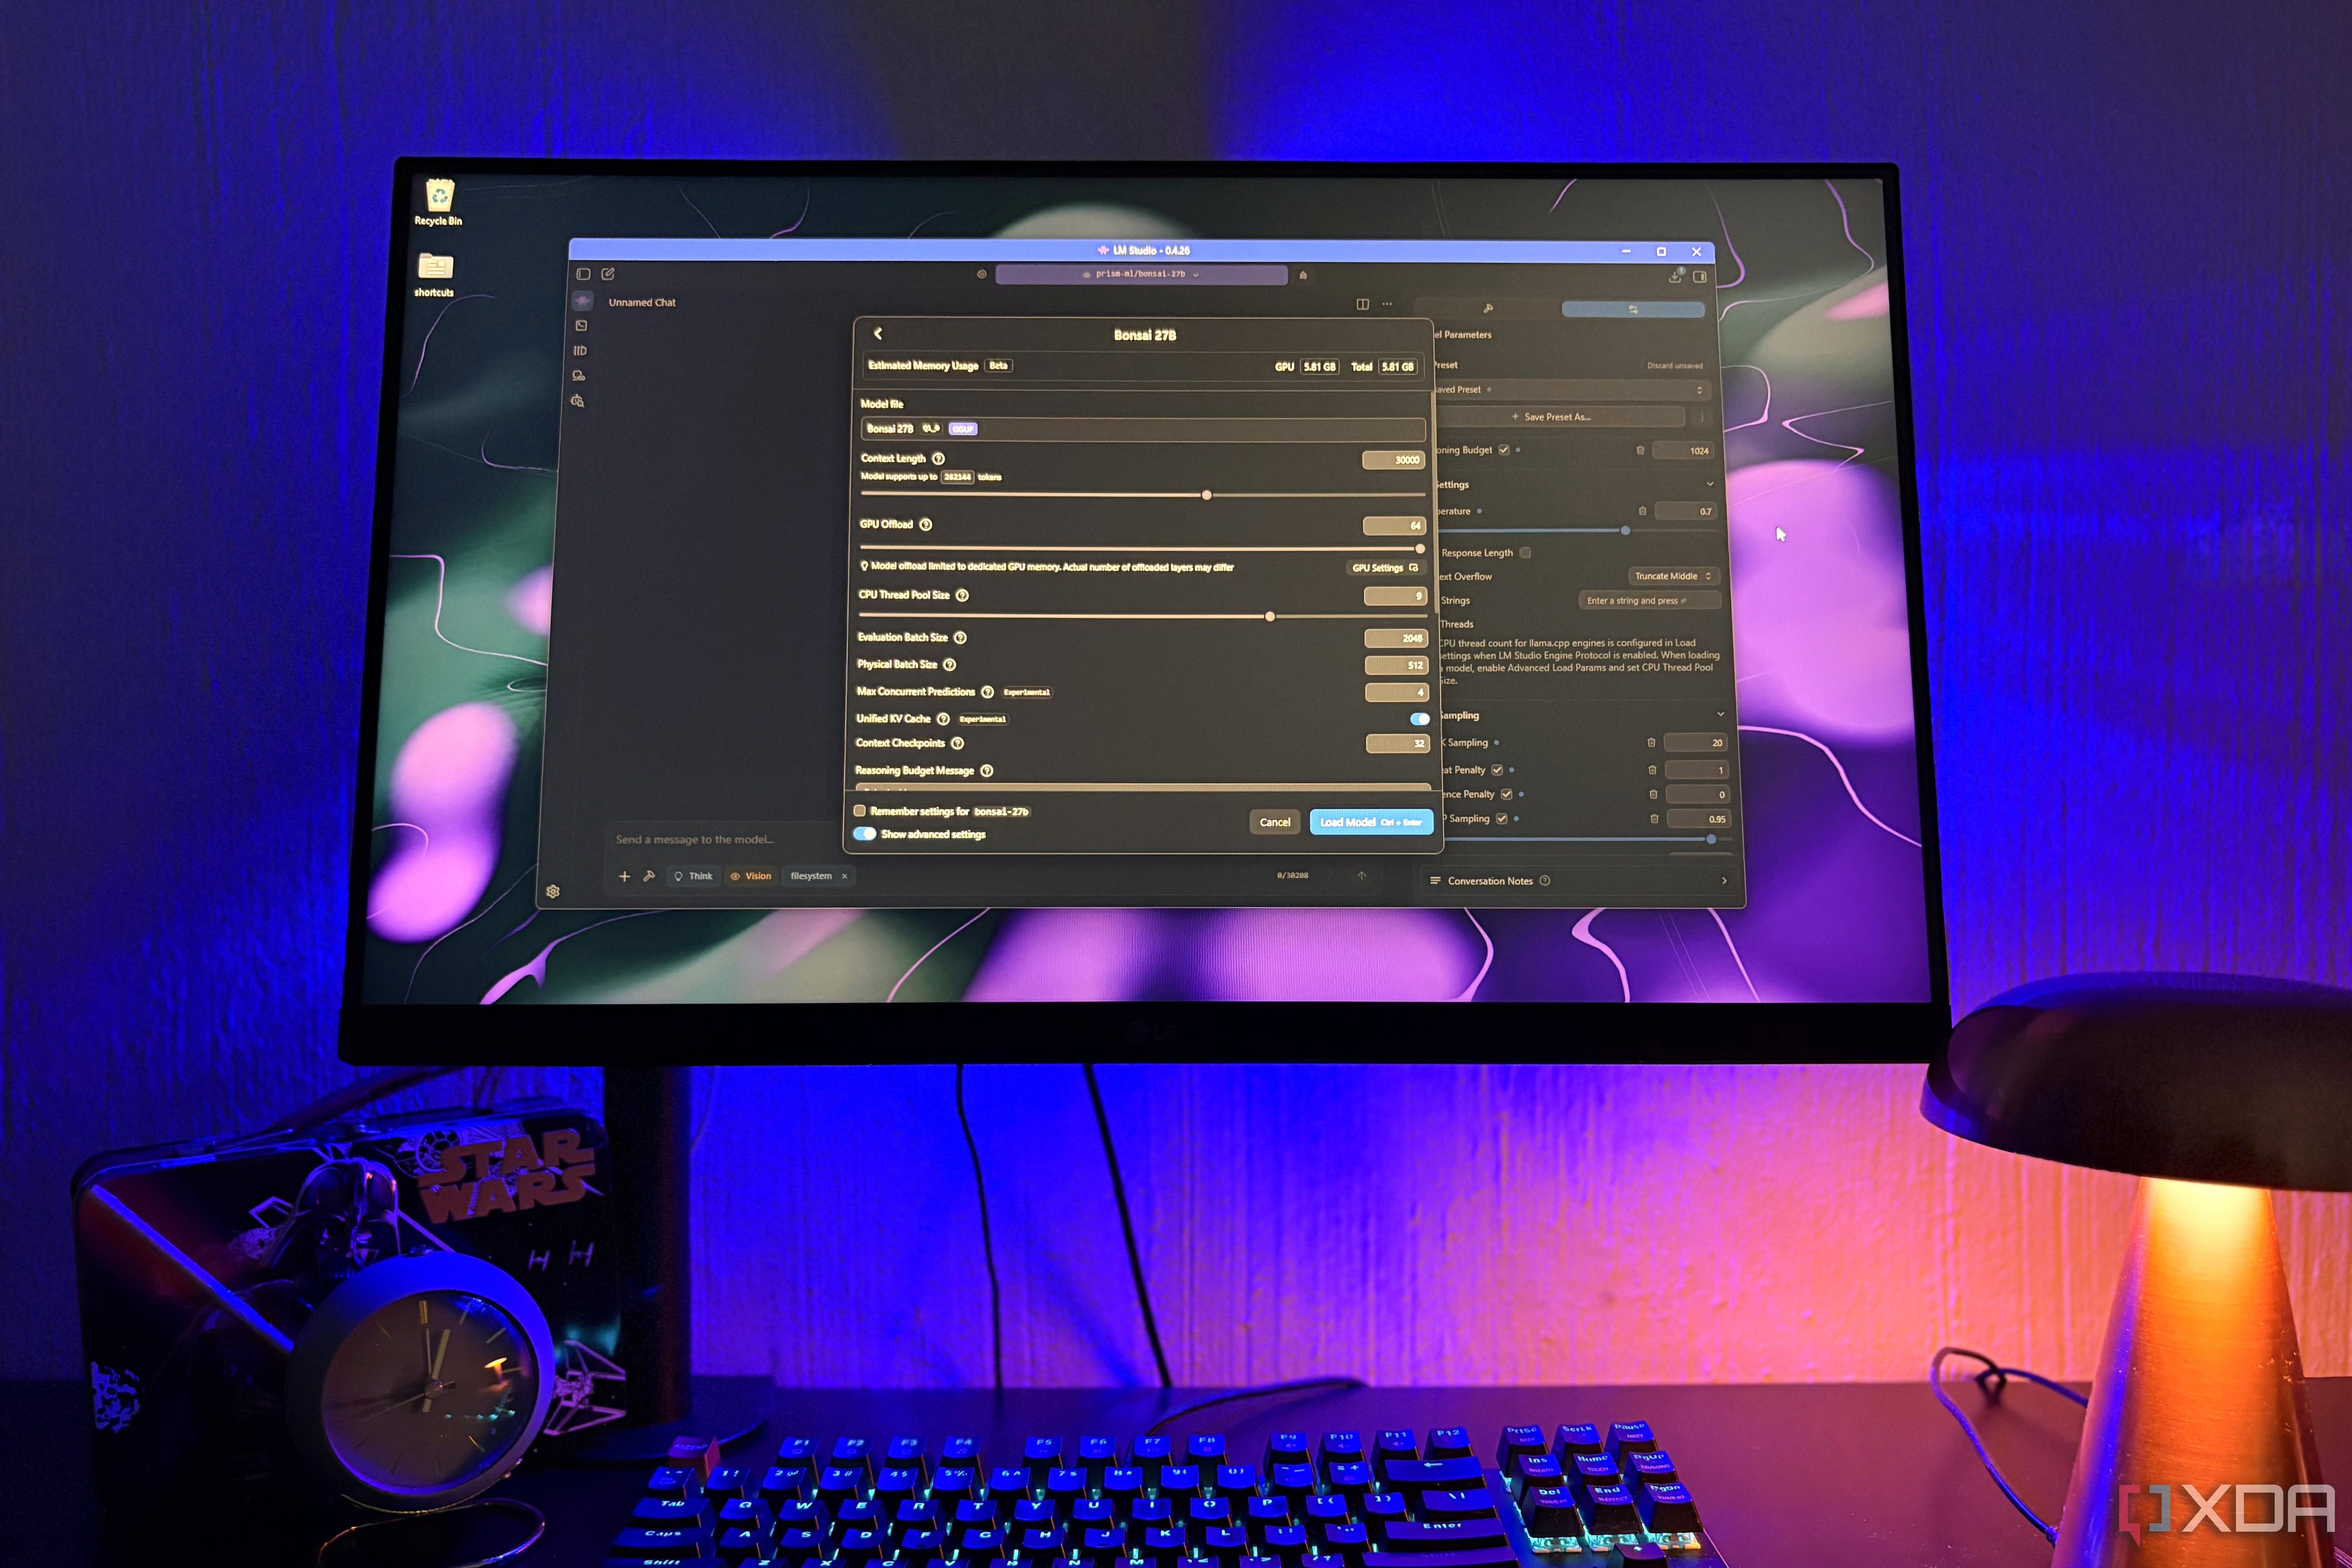
I stopped chasing bigger local models, and a 27B model on my 8GB GPU does more of what I need
XDA Developers
XDA Developers news
View Channel →
I stopped chasing bigger local models, and a 27B model on my 8GB GPU does more of what I need
Source ↗ 👁 1 💬 0
Running local models on a smaller card almost always comes with a ceiling, so you really have no choice but to live somewhere around the 4B to 9B mark. Every few weeks a new Qwen release seems to land on Hugging Face with bigger numbers attached, and the urge is to grab the largest version that might squeeze onto my card. Usually, it doesn't fit. Or it does, but with half the model sitting in system RAM, and answers crawl out a word at a time.

Comments (0)

Sign in to join the discussion

More Like This

Incremental iOS 27.2.1, iPadOS, macOS updates arrive with bug fixes
AppleInsider News · 1h ago
📰
Meta releases Muse Ember, its smallest and most cost-efficient AI model yet, saying it delivers more intelligence per dollar than Haiku 5.5 and GPT-6 Luna (Russell Brandom/TechCrunch)
Techmeme · 1h ago
Apple Releases macOS Golden Gate 27.2.1
MacRumors: Mac News and Rumors - All Stories · 1h ago
Even Razer Is Getting Into Wired Earbuds
Gizmodo · 1h ago
Apple Releases iOS 27.2.1 With Bug Fixes
MacRumors: Mac News and Rumors - All Stories · 1h ago
📰
Jensen Huang’s affair with alleged Chinese spy puts Nvidia’s China ambitions under scrutiny
TechCrunch · 1h ago